

«میانای برنامهسازی کاربردی Gemini» ازطریق ابزار «جستجوی فایل»، «تولید با کمک بازیابی» ("RAG") را فعال میکند. «جستجوی فایل» دادههای شما را وارد، دستهبندی، و نمایهگذاری میکند تا براساس پیامواره ارائهشده، بازیابی سریع اطلاعات مرتبط را امکانپذیر کند. این اطلاعات بازیابیشده سپس بهعنوان زمینه برای مدل استفاده میشود و به آن امکان میدهد پاسخهای دقیقتر و مرتبطتری ارائه دهد. جستجوی فایل همچنین میتواند با جاسازیهای نوشتاری پشتیبانیشده توسط gemini-embedding-001 و جاسازی تصویر/چندحالته پشتیبانیشده توسط gemini-embedding-2، قابلیتهای چندحالته ارائه دهد.
ذخیرهسازی فایل و تولید جاسازی در زمان پُرسمان رایگان است و فقط برای ایجاد جاسازیها هنگام نمایهگذاری اولیه فایلها و هزینه عادی واحدهای ورودی / خروجی مدل Gemini پرداخت خواهید کرد. این الگوی جدید صورتحساب باعث میشود ساختن و مقیاسبندی «ابزار جستجوی فایل» آسانتر و مقرونبهصرفهتر شود. برای جزئیات، بخش قیمتگذاری را ببینید.
مستقیماً در فروشگاه «جستجوی فایل» بارگذاری کنید
این مثال نشان میدهد که چگونه میتوان یک فایل را مستقیماً در فروشگاه جستجوی فایل بارگذاری کرد:
Python
from google import genai
from google.genai import types
import time

client = genai.Client()

# File name will be visible in citations
file_search_store = client.file_search_stores.create(
    config={
        'display_name': 'your-fileSearchStore-name',
        'embedding_model': 'models/gemini-embedding-2'
    }
)

operation = client.file_search_stores.upload_to_file_search_store(
  file='sample.txt',
  file_search_store_name=file_search_store.name,
  config={
      'display_name' : 'display-file-name',
  }
)

while not operation.done:
    time.sleep(5)
    operation = client.operations.get(operation)

response = client.models.generate_content(
    model="gemini-3.8-flash",
    contents="""Can you tell me about [insert question]""",
    config=types.GenerateContentConfig(
        tools=[
            types.Tool(
                file_search=types.FileSearch(
                    file_search_store_names=[file_search_store.name]
                )
            )
        ]
    )
)

print(response.text)
JavaScript
const { GoogleGenAI } = require('@google/genai');

const ai = new GoogleGenAI({});

async function run() {
  // File name will be visible in citations
  const fileSearchStore = await ai.fileSearchStores.create({
    config: {
      displayName: 'your-fileSearchStore-name',
      embeddingModel: 'models/gemini-embedding-2'
    }
  });

  let operation = await ai.fileSearchStores.uploadToFileSearchStore({
    file: 'file.txt',
    fileSearchStoreName: fileSearchStore.name,
    config: {
      displayName: 'file-name',
    }
  });

  while (!operation.done) {
    await new Promise(resolve => setTimeout(resolve, 5000));
    operation = await ai.operations.get({ operation });
  }

  const response = await ai.models.generateContent({
    model: "gemini-3.8-flash",
    contents: "Can you tell me about [insert question]",
    config: {
      tools: [
        {
          fileSearch: {
            fileSearchStoreNames: [fileSearchStore.name]
          }
        }
      ]
    }
  });

  console.log(response.text);
}

run();
برای اطلاعات بیشتر، مرجع میانای برنامهسازی کاربردی برای uploadToFileSearchStore را بررسی کنید.
درحال وارد کردن فایلها
یا میتوانید فایل موجودی را بارگذاری کنید و آن را به فروشگاه جستجوی فایل خود وارد کنید:
Python
from google import genai
from google.genai import types
import time

client = genai.Client()

# File name will be visible in citations
sample_file = client.files.upload(file='sample.txt', config={'name': 'display_file_name'})

file_search_store = client.file_search_stores.create(
    config={
        'display_name': 'your-fileSearchStore-name',
        'embedding_model': 'models/gemini-embedding-2'
    }
)

operation = client.file_search_stores.import_file(
    file_search_store_name=file_search_store.name,
    file_name=sample_file.name
)

while not operation.done:
    time.sleep(5)
    operation = client.operations.get(operation)

response = client.models.generate_content(
    model="gemini-3.8-flash",
    contents="""Can you tell me about [insert question]""",
    config=types.GenerateContentConfig(
        tools=[
            types.Tool(
                file_search=types.FileSearch(
                    file_search_store_names=[file_search_store.name]
                )
            )
        ]
    )
)

print(response.text)
JavaScript
const { GoogleGenAI } = require('@google/genai');

const ai = new GoogleGenAI({});

async function run() {
  // File name will be visible in citations
  const sampleFile = await ai.files.upload({
    file: 'sample.txt',
    config: { name: 'file-name' }
  });

  const fileSearchStore = await ai.fileSearchStores.create({
    config: {
      displayName: 'your-fileSearchStore-name',
      embeddingModel: 'models/gemini-embedding-2'
    }
  });

  let operation = await ai.fileSearchStores.importFile({
    fileSearchStoreName: fileSearchStore.name,
    fileName: sampleFile.name
  });

  while (!operation.done) {
    await new Promise(resolve => setTimeout(resolve, 5000));
    operation = await ai.operations.get({ operation: operation });
  }

  const response = await ai.models.generateContent({
    model: "gemini-3.8-flash",
    contents: "Can you tell me about [insert question]",
    config: {
      tools: [
        {
          fileSearch: {
            fileSearchStoreNames: [fileSearchStore.name]
          }
        }
      ]
    }
  });

  console.log(response.text);
}

run();
برای اطلاعات بیشتر، مرجع میانای برنامهسازی کاربردی برای importFile را بررسی کنید.
پیکربندی تکهتکه کردن
وقتی فایلی را به فروشگاه «جستجوی فایل» وارد میکنید، بهطور خودکار به
تکههایی تقسیم میشود، جاسازی میشود، نمایهگذاری میشود، و در فروشگاه «جستجوی فایل» شما بارگذاری میشود. اگر به کنترل بیشتری روی استراتژی تکهتکه کردن نیاز دارید، میتوانید تنظیم chunking_config را مشخص کنید تا حداکثر تعداد دادهواحد در هر تکه و حداکثر تعداد دادهواحدهای همپوشانی را تنظیم کنید.
Python
from google import genai
from google.genai import types
import time

client = genai.Client()

operation = client.file_search_stores.upload_to_file_search_store(
    file_search_store_name=file_search_store.name,
    file_name=sample_file.name,
    config={
        'chunking_config': {
          'white_space_config': {
            'max_tokens_per_chunk': 200,
            'max_overlap_tokens': 20
          }
        }
    }
)

while not operation.done:
    time.sleep(5)
    operation = client.operations.get(operation)

print("Custom chunking complete.")
JavaScript
const { GoogleGenAI } = require('@google/genai');

const ai = new GoogleGenAI({});

let operation = await ai.fileSearchStores.uploadToFileSearchStore({
  file: 'file.txt',
  fileSearchStoreName: fileSearchStore.name,
  config: {
    displayName: 'file-name',
    chunkingConfig: {
      whiteSpaceConfig: {
        maxTokensPerChunk: 200,
        maxOverlapTokens: 20
      }
    }
  }
});

while (!operation.done) {
  await new Promise(resolve => setTimeout(resolve, 5000));
  operation = await ai.operations.get({ operation });
}
console.log("Custom chunking complete.");
برای استفاده از فروشگاه «جستجوی فایل»، آن را بهعنوان ابزار به روش generateContent
ارسال کنید، همانطور که در مثالهای بارگذاری و وارد کردن نشان داده شده است.
روش کار
«جستجوی فایل» از تکنیکی بهنام «جستجوی معنایی» برای یافتن اطلاعات مرتبط با پیامواره کاربر استفاده میکند. برخلاف جستجوی استاندارد براساس کلیدواژه، جستجوی معنایی معنی و بافت پُرسمان شما را درک میکند.
وقتی فایلی را وارد میکنید، به نمایشهای عددی به نام جاسازی تبدیل میشود که معنای معنایی محتوای بارگذاریشده را ضبط میکند. این جاسازیها در پایگاه داده تخصصی «جستجوی فایل» ذخیره میشود. وقتی پُرسمانی انجام میدهید، آن پُرسمان نیز به جاسازی تبدیل میشود. سپس سیستم «جستجوی فایل» را اجرا میکند تا مشابهترین و مرتبطترین بخشهای سند را از فروشگاه «جستجوی فایل» پیدا کند.
برای جاسازیها «زمان زنده بودن» (TTL) وجود ندارد؛ آنها تا زمانی که بهصورت دستی حذف شوند یا زمانی که مدل منسوخ شود، باقی میمانند. فایلها، بااینحال، پساز ۴۸ ساعت حذف میشوند.
در اینجا تفکیک فرایند استفاده از «میانای برنامهسازی کاربردی جستجوی فایل»
uploadToFileSearchStore آمده است:
ایجاد فروشگاه «جستجوی فایل»: فروشگاه «جستجوی فایل» حاوی دادههای پردازششده از فایلهای شما است. این محتوی پایدار برای جاسازیهایی است که جستجوی معنایی روی آنها عمل میکند.
بارگذاری فایل و وارد کردن در فروشگاه «جستجوی فایل»: بهطور همزمان فایلی را بارگذاری کنید و نتایج را در فروشگاه «جستجوی فایل» وارد کنید. این کار یک شیء
Fileموقت ایجاد میکند که مرجعی برای سند خام شما است. سپس آن دادهها تکهتکه میشوند، به جاسازیهای «جستجوی فایل» تبدیل میشوند، و نمایهگذاری میشوند.Fileشیء پساز ۴۸ ساعت حذف میشود، درحالیکه دادههای واردشده به فروشگاه «جستجوی فایل» تا زمانی که خودتان آنها را حذف نکنید برای همیشه ذخیره میشوند.پُرسمان با «جستجوی فایل»: درنهایت، از ابزار
FileSearchدر تماسgenerateContentاستفاده میکنید. در پیکربندی ابزار،FileSearchRetrievalResourceرا مشخص میکنید که بهFileSearchStoreموردنظرتان برای جستجو اشاره میکند. این دستور به مدل میگوید که در آن فروشگاه «جستجوی فایل» خاص، جستجوی معنایی انجام دهد تا اطلاعات مربوطه را برای پاسخ خود پیدا کند.
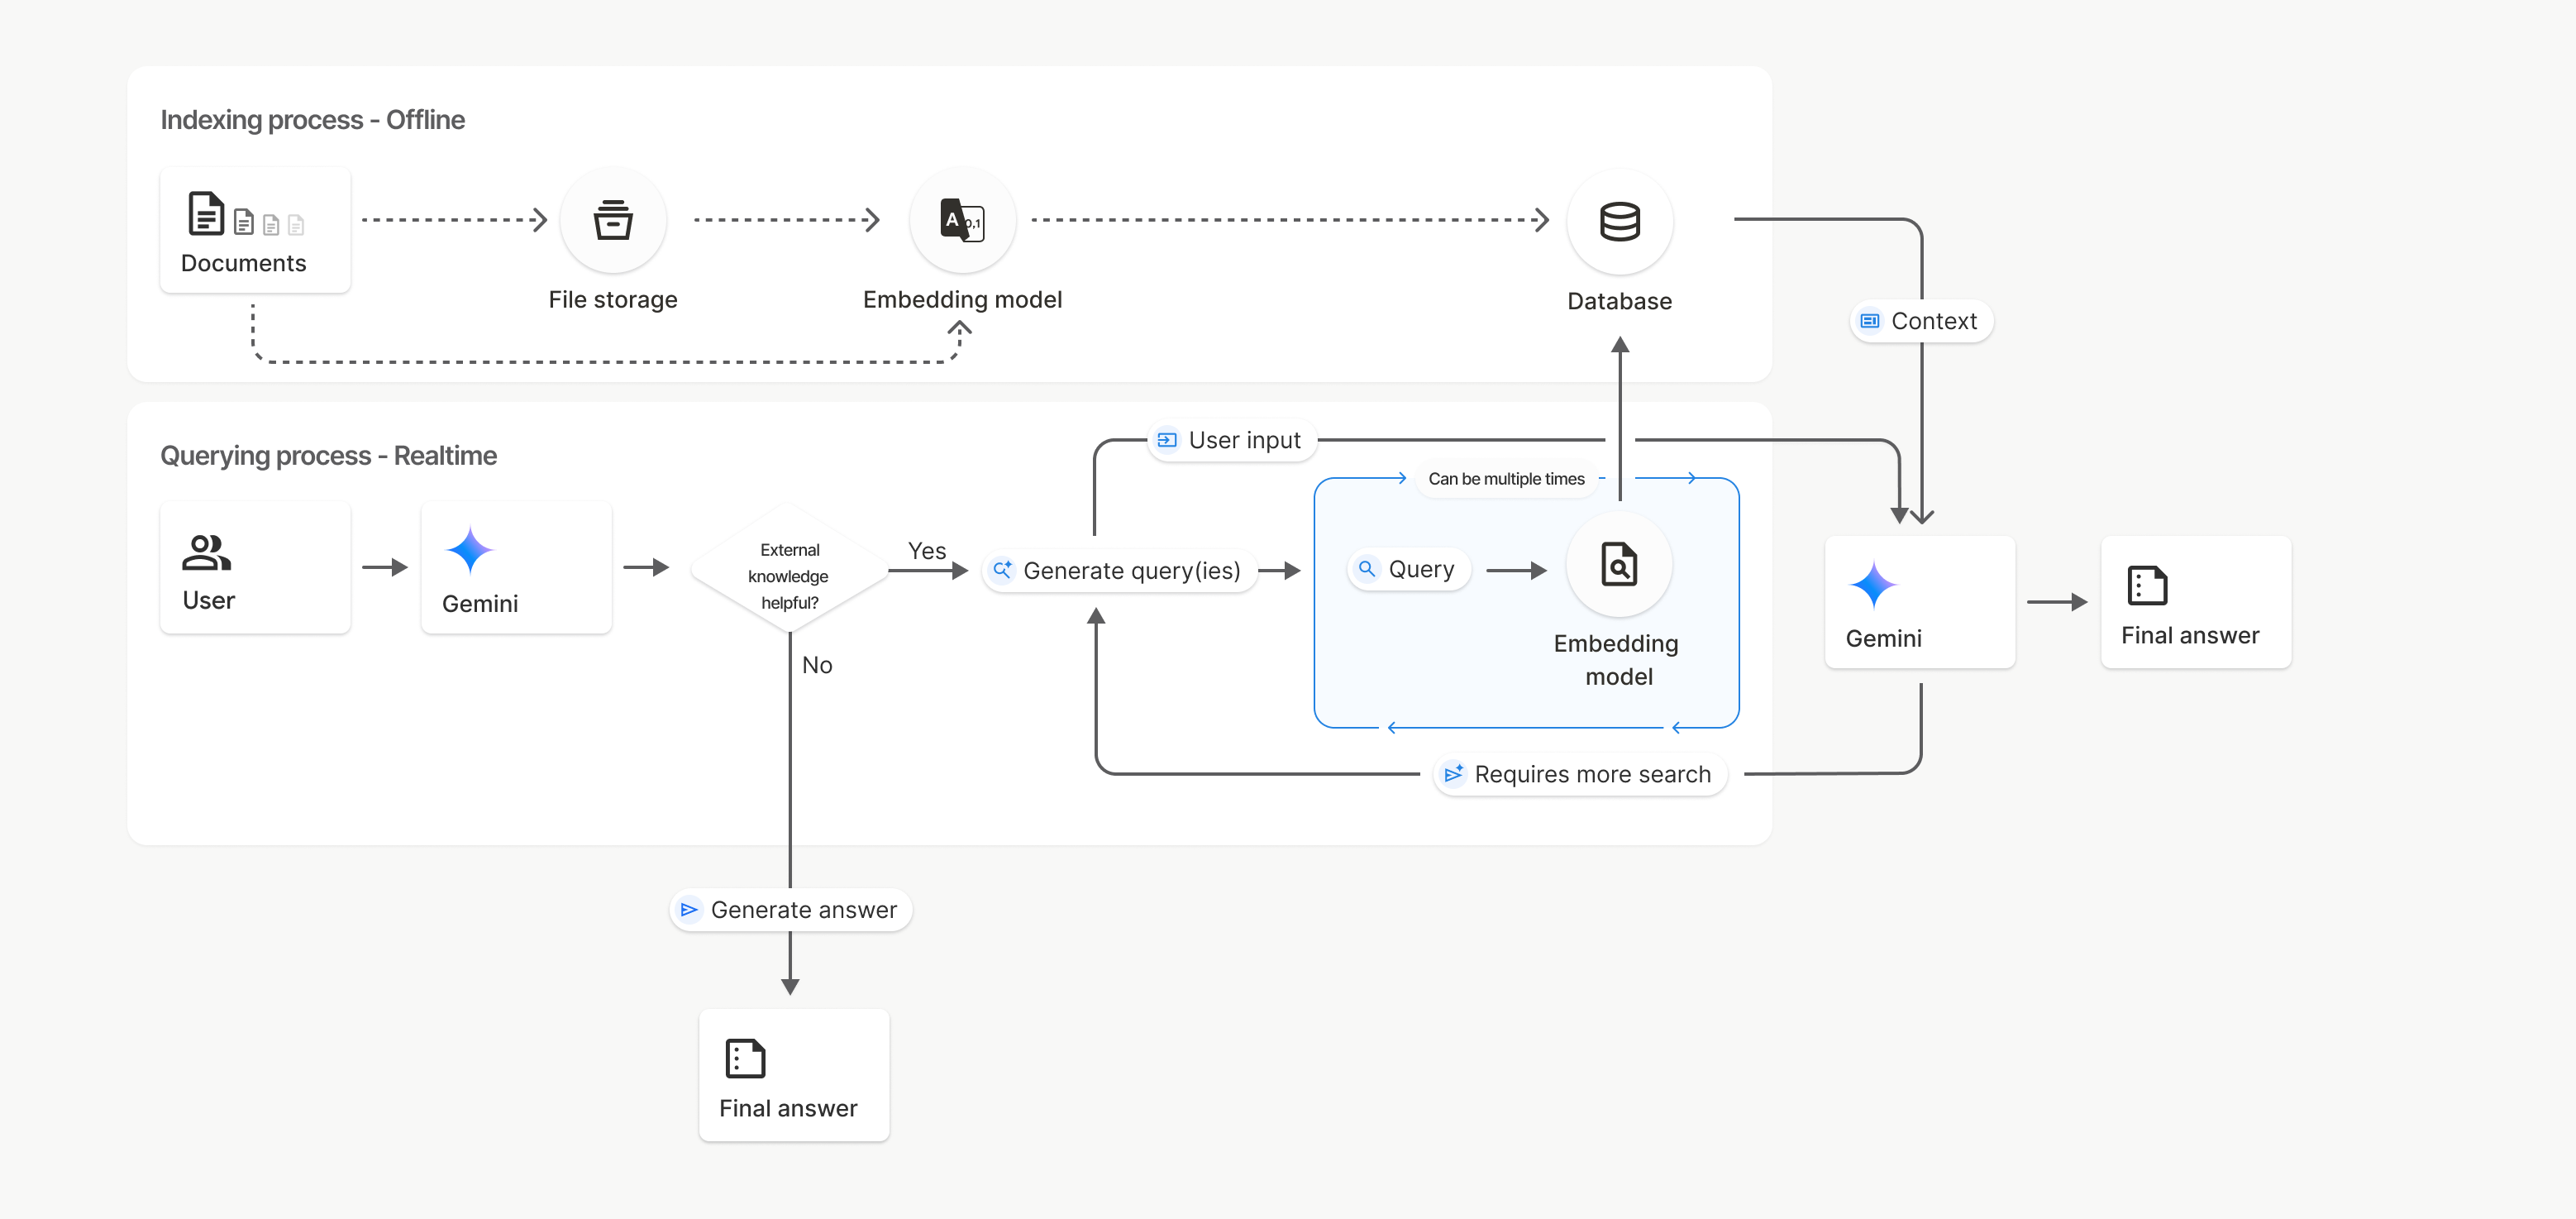
در این نمودار، خط نقطهچین از اسناد به مدل جاسازی
(بااستفاده از gemini-embedding-001)
نشاندهنده uploadToFileSearchStore API (دور زدن ذخیرهسازی فایل) است.
درغیراینصورت، استفاده از Files API برای ایجاد جداگانه
و سپس وارد کردن فایلها، فرایند نمایهگذاری را از Documents به
File storage و سپس به Embedding model منتقل میکند.
فروشگاههای «جستجوی فایل»
فروشگاه «جستجوی فایل» محفظهای برای جاسازیهای سند شما است. درحالیکه فایلهای خام
بارگذاریشده ازطریق «میانای برنامهسازی کاربردی فایل» پساز ۴۸ ساعت حذف میشوند، دادههای واردشده به
فروشگاه «جستجوی فایل» تا زمانیکه آنها را بهطور دستی حذف نکنید برای همیشه ذخیره میشوند. میتوانید
چند فروشگاه «جستجوی فایل» ایجاد کنید تا اسنادتان را سازماندهی کنید. میانای برنامهسازی کاربردی
FileSearchStore به شما امکان میدهد برای مدیریت فروشگاههای جستجوی فایل، ایجاد، فهرست کردن، دریافت، و حذف کنید. نامهای فروشگاه «جستجوی فایل» در سطح جهانی محدود شدهاند.
در اینجا چند نمونه از نحوه مدیریت فروشگاههای «جستجوی فایل» آورده شده است:
Python
file_search_store = client.file_search_stores.create(
    config={
        'display_name': 'my-file_search-store-123',
        'embedding_model': 'models/gemini-embedding-2'
    }
)

for file_search_store in client.file_search_stores.list():
    print(file_search_store)

my_file_search_store = client.file_search_stores.get(name='fileSearchStores/my-file_search-store-123')

client.file_search_stores.delete(name='fileSearchStores/my-file_search-store-123', config={'force': True})
JavaScript
const fileSearchStore = await ai.fileSearchStores.create({
  config: {
    displayName: 'my-file_search-store-123',
    embeddingModel: 'models/gemini-embedding-2'
  }
});

const fileSearchStores = await ai.fileSearchStores.list();
for await (const store of fileSearchStores) {
  console.log(store);
}

const myFileSearchStore = await ai.fileSearchStores.get({
  name: 'fileSearchStores/my-file_search-store-123'
});

await ai.fileSearchStores.delete({
  name: 'fileSearchStores/my-file_search-store-123',
  config: { force: true }
});
REST
curl -X POST "https://generativelanguage.googleapis.com/v1beta/fileSearchStores?key=${GEMINI_API_KEY}" \
    -H "Content-Type: application/json" \
    -d '{ "displayName": "My Store", "embedding_model": "models/gemini-embedding-2" }'

curl "https://generativelanguage.googleapis.com/v1beta/fileSearchStores?key=${GEMINI_API_KEY}" \

curl "https://generativelanguage.googleapis.com/v1beta/fileSearchStores/my-file_search-store-123?key=${GEMINI_API_KEY}"

curl -X DELETE "https://generativelanguage.googleapis.com/v1beta/fileSearchStores/my-file_search-store-123?key=${GEMINI_API_KEY}"
اسناد «جستجوی فایل»
بااستفاده از
File Search Documents API میتوانید سندهای جداگانه را در فروشگاههای فایل مدیریت کنید تا هر سند را در فروشگاه جستجوی فایل list کنید،
اطلاعات مربوط به سند را get کنید، و سند را براساس نام delete کنید.
Python
for document_in_store in client.file_search_stores.documents.list(parent='fileSearchStores/my-file_search-store-123'):
  print(document_in_store)

file_search_document = client.file_search_stores.documents.get(name='fileSearchStores/my-file_search-store-123/documents/my_doc')
print(file_search_document)

client.file_search_stores.documents.delete(name='fileSearchStores/my-file_search-store-123/documents/my_doc')
JavaScript
const documents = await ai.fileSearchStores.documents.list({
  parent: 'fileSearchStores/my-file_search-store-123'
});
for await (const doc of documents) {
  console.log(doc);
}

const fileSearchDocument = await ai.fileSearchStores.documents.get({
  name: 'fileSearchStores/my-file_search-store-123/documents/my_doc',
});

await ai.fileSearchStores.documents.delete({
  name: 'fileSearchStores/my-file_search-store-123/documents/my_doc'
});
REST
curl "https://generativelanguage.googleapis.com/v1beta/fileSearchStores/my-file_search-store-123/documents?key=${GEMINI_API_KEY}"

curl "https://generativelanguage.googleapis.com/v1beta/fileSearchStores/my-file_search-store-123/documents/my_doc?key=${GEMINI_API_KEY}"

curl -X DELETE "https://generativelanguage.googleapis.com/v1beta/fileSearchStores/my-file_search-store-123/documents/my_doc?key=${GEMINI_API_KEY}"
فرادادههای فایل
میتوانید به فایلهایتان فراداده سفارشی اضافه کنید تا به فیلتر کردن آنها کمک کنید یا بافت بیشتری ارائه دهید. فراداده مجموعهای از جفتهای کلید-مقدار است.
Python
op = client.file_search_stores.import_file(
    file_search_store_name=file_search_store.name,
    file_name=sample_file.name,
    custom_metadata=[
        {"key": "author", "string_value": "Robert Graves"},
        {"key": "year", "numeric_value": 1934}
    ]
)
JavaScript
let operation = await ai.fileSearchStores.importFile({
  fileSearchStoreName: fileSearchStore.name,
  fileName: sampleFile.name,
  config: {
    customMetadata: [
      { key: "author", stringValue: "Robert Graves" },
      { key: "year", numericValue: 1934 }
    ]
  }
});
این ویژگی زمانی مفید است که چندین سند در فروشگاه «جستجوی فایل» داشته باشید و بخواهید فقط زیرمجموعهای از آنها را جستجو کنید.
Python
response = client.models.generate_content(
    model="gemini-3.8-flash",
    contents="Tell me about the book 'I, Claudius'",
    config=types.GenerateContentConfig(
        tools=[
            types.Tool(
                file_search=types.FileSearch(
                    file_search_store_names=[file_search_store.name],
                    metadata_filter="author=Robert Graves",
                )
            )
        ]
    )
)

print(response.text)
JavaScript
const response = await ai.models.generateContent({
  model: "gemini-3.8-flash",
  contents: "Tell me about the book 'I, Claudius'",
  config: {
    tools: [
      {
        fileSearch: {
          fileSearchStoreNames: [fileSearchStore.name],
          metadataFilter: 'author="Robert Graves"',
        }
      }
    ]
  }
});

console.log(response.text);
REST
curl "https://generativelanguage.googleapis.com/v1beta/models/gemini-3.8-flash:generateContent?key=${GEMINI_API_KEY}" \
    -H 'Content-Type: application/json' \
    -X POST \
    -d '{
            "contents": [{
                "parts":[{"text": "Tell me about the book I, Claudius"}]
            }],
            "tools": [{
                "file_search": {
                    "file_search_store_names":["'$STORE_NAME'"],
                    "metadata_filter": "author = \"Robert Graves\""
                }
            }]
        }' 2> /dev/null > response.json

cat response.json
راهنمایی درباره پیادهسازی دستورگان فیلتر فهرست برای metadata_filter را میتوانید
در google.aip.dev/160 پیدا کنید
جستجوی چندحالته فایل
«جستجوی فایل چندوجهی» به شما امکان میدهد تصاویر را بهصورت بومی جاسازی و در آنها جستجو کنید و برنامههای RAG چندوجهی غنی را فعال کنید.
پیکربندی مدل جاسازی
وقتی FileSearchStore ایجاد میکنید، باید مدل جاسازی فقط نوشتاری پیشفرض را ملغی کنید تا از مدل چندحالته استفاده کنید. از models/gemini-embedding-2 برای
پردازش نوشتار و تصویر استفاده کنید.
Python
store = client.file_search_stores.create(
    config={
        "display_name": "Multimodal Catalog",
        "embedding_model": "models/gemini-embedding-2",
    }
)
JavaScript
const fileSearchStore = await ai.fileSearchStores.create({
  config: {
    displayName: "Multimodal Catalog",
    embeddingModel: "models/gemini-embedding-2",
  },
});
REST
curl -X POST "https://generativelanguage.googleapis.com/v1beta/fileSearchStores?key=$GEMINI_API_KEY" \
    -H "Content-Type: application/json" \
    -d '{
      "display_name": "Multimodal Catalog",
      "embedding_model": "models/gemini-embedding-2"
    }'
بارگذاری کردن تصویرها
پساز ایجاد فروشگاه با مدل جاسازی چندوجهی، میتوانید فایلهای تصویری را مستقیماً بااستفاده از همان میاناهای برنامهسازی کاربردی بارگذاری که در بارگذاری مستقیم در فروشگاه «جستجوی فایل» یا وارد کردن فایلها توضیح داده شده است بارگذاری کنید.
الزامات فایل تصویر:
- وضوح فایلهای تصویر باید حداکثر ۴K x ۴K پیکسل باشد.
- قالبهای پشتیبانیشده عبارتاند از PNG، JPEG.
نقلقولها
وقتی از «جستجوی فایل» استفاده میکنید، پاسخ مدل ممکن است شامل استنادهایی باشد که مشخص میکنند از کدام بخشهای سندهای بارگذاریشده شما برای تولید پاسخ استفاده شده است. این کار به درستیسنجی و تأیید کمک میکند.
میتوانید ازطریق ویژگی grounding_metadata در پاسخ به اطلاعات ارجاع دسترسی پیدا کنید.
Python
print(response.candidates[0].grounding_metadata)
JavaScript
console.log(JSON.stringify(response.candidates?.[0]?.groundingMetadata, null, 2));
برای کسب اطلاعات دقیق درباره ساختار فراداده زمینهسازی، به مثالهای کتابچه جستجوی فایل یا بخش زمینهسازی در اسناد زمینهسازی با «جستجوی Google» مراجعه کنید.
شماره صفحه
وقتی از «جستجوی فایل» با اسنادی که صفحه دارند (مثل PDF) استفاده میکنید، پاسخ مدل ممکن است شامل شماره صفحهای باشد که اطلاعات در آن پیدا شده است.
ازطریق ویژگی page_number در
retrieved_context میتوانید به این اطلاعات دسترسی پیدا کنید.
Python
# Iterate through citations and check for page numbers
for chunk in response.grounding_metadata.grounding_chunks:
   if chunk.retrieved_context and chunk.retrieved_context.page_number:
       print(f"Cited Page: {chunk.retrieved_context.page_number}")
JavaScript
const groundingMetadata = response.candidates[0].groundingMetadata;
for (const chunk of groundingMetadata.groundingChunks) {
  if (chunk.retrievedContext && chunk.retrievedContext.pageNumber) {
    console.log(`Cited Page: ${chunk.retrievedContext.pageNumber}`);
  }
}
نقلقولهای رسانهای
وقتی مدل درطول تولید به یک بخش تصویر ارجاع میدهد، API یک
استناد در فرادادههای زمینهای برمیگرداند که شامل media_id است. میتوانید از این
شناسه برای بارگیری کردن تکه تصویر دقیقی که مدل به آن ارجاع داده است استفاده کنید. این media_id در چندین فراخوانی جستجو ماندگار است، که به شما امکان میدهد
تصویر یکسان را بهطور قابلاعتمادی بازیابی کنید یا آن را بااستفاده از شناسه در حافظه نهان ذخیره کنید.
تکهکد زیر نمونهای از پاسخ REST است:
"groundingMetadata": {
  "groundingChunks": [
    {
      "retrievedContext": {
        "title": "product_image",
        "fileSearchStore": "fileSearchStores/my-store-123",
        "media_id": "fileSearchStores/my-store-123/media/BlobId-456"
      }
    }
  ]
}
تکهکدهای زیر نحوه بازیابی media_id و
بارگیری رسانه را نشان میدهند:
Python
# Iterate through citations and download media if present
for chunk in response.grounding_metadata.grounding_chunks:
   if chunk.retrieved_context and chunk.retrieved_context.media_id:
       print(f"Cited Media ID: {chunk.retrieved_context.media_id}")
       # Download the blob using the SDK
       blob_content = client.file_search_stores.download_media(
           media_id=chunk.retrieved_context.media_id
       )
       # Save blob_content to file...
JavaScript
const groundingMetadata = response.candidates[0].groundingMetadata;
for (const chunk of groundingMetadata.groundingChunks) {
  if (chunk.retrievedContext && chunk.retrievedContext.mediaId) {
    console.log(`Cited Media ID: ${chunk.retrievedContext.mediaId}`);
    const blobContent = await ai.fileSearchStores.downloadMedia(chunk.retrievedContext.mediaId);
    // Save blobContent to file...
  }
}
REST
curl -X GET "https://generativelanguage.googleapis.com/v1/fileSearchStores/my-store-123/media/BlobId-456" \
  -H "x-goog-api-key: $GEMINI_API_KEY"
فراداده سفارشی در دادههای زمینهای
اگر به فایلهایتان فراداده سفارشی اضافه کردهاید، میتوانید در فراداده زمینهای پاسخ مدل به آن دسترسی داشته باشید. این ویژگی برای انتقال بافت اضافی (مثل نشانیهای وب، شماره صفحهها، یا نویسندگان) از اسناد منبع به منطق برنامه شما مفید است. هر grounding_chunk در
retrieved_context حاوی این فراداده سفارشی است.
Python
response = client.models.generate_content(
    model="gemini-3.8-flash",
    contents="Tell me about [insert question]",
    config=types.GenerateContentConfig(
        tools=[
            types.Tool(
                file_search=types.FileSearch(
                    file_search_store_names=[file_search_store.name]
                )
            )
        ]
    )
)

for chunk in response.candidates[0].grounding_metadata.grounding_chunks:
    if chunk.retrieved_context:
        print(f"Text: {chunk.retrieved_context.text}")
        if chunk.retrieved_context.custom_metadata:
            for metadata in chunk.retrieved_context.custom_metadata:
                print(f"Metadata Key: {metadata.key}")
                print(f"Value: {metadata.string_value or metadata.numeric_value}")
JavaScript
const response = await ai.models.generateContent({
  model: "gemini-3.8-flash",
  contents: "Tell me about [insert question]",
  config: {
    tools: [
      {
        fileSearch: {
          fileSearchStoreNames: [fileSearchStore.name]
        }
      }
    ]
  }
});

const groundingMetadata = response.candidates[0].groundingMetadata;
groundingMetadata.groundingChunks.forEach((chunk) => {
  if (chunk.retrievedContext) {
    console.log(`Text: ${chunk.retrievedContext.text}`);
    if (chunk.retrievedContext.customMetadata) {
      chunk.retrievedContext.customMetadata.forEach((metadata) => {
        console.log(`Metadata Key: ${metadata.key}`);
        console.log(`Value: ${metadata.stringValue || metadata.numericValue}`);
      });
    }
  }
});
REST
{
  "candidates": [
    {
      "content": { ... },
      "grounding_metadata": {
        "grounding_chunks": [
          {
            "retrieved_context": {
              "text": "...",
              "title": "...",
              "uri": "...",
              "custom_metadata": [
                {
                  "key": "author",
                  "string_value": "Robert Graves"
                },
                {
                  "key": "year",
                  "numeric_value": 1934
                }
              ]
            }
          }
        ],
        "grounding_supports": [ ... ]
      }
    }
  ]
}
برونداد ساختاریافته
با شروع از مدلهای Gemini 3، میتوانید ابزار جستجوی فایل را با بروندادهای ساختاریافته ترکیب کنید.
Python
from pydantic import BaseModel, Field

class Money(BaseModel):
    amount: str = Field(description="The numerical part of the amount.")
    currency: str = Field(description="The currency of amount.")

response = client.models.generate_content(
    model="gemini-3.8-flash",
    contents="What is the minimum hourly wage in Tokyo right now?",
    config=types.GenerateContentConfig(
                tools=[
                    types.Tool(
                        file_search=types.FileSearch(
                            file_search_store_names=[file_search_store.name]
                        )
                    )
                ],
                response_format={"text": {"mime_type": "application/json", "schema": Money.model_json_schema()}}
      )
)
result = Money.model_validate_json(response.text)
print(result)
JavaScript
import { z } from "zod";

const moneySchema = z.object({
  amount: z.string().describe("The numerical part of the amount."),
  currency: z.string().describe("The currency of amount."),
});

async function run() {
  const response = await ai.models.generateContent({
    model: "gemini-3.8-flash",
    contents: "What is the minimum hourly wage in Tokyo right now?",
    config: {
      tools: [
        {
          fileSearch: {
            fileSearchStoreNames: [file_search_store.name],
          },
        },
      ],
      responseFormat: { text: { mimeType: "application/json", schema: z.toJSONSchema(moneySchema) } },
    },
  });

  const result = moneySchema.parse(JSON.parse(response.text));
  console.log(result);
}

run();
REST
curl "https://generativelanguage.googleapis.com/v1beta/models/gemini-3.8-flash:generateContent" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H 'Content-Type: application/json' \
  -X POST \
  -d '{
    "contents": [{
      "parts": [{"text": "What is the minimum hourly wage in Tokyo right now?"}]
    }],
    "tools": [
      {
        "fileSearch": {
          "fileSearchStoreNames": ["$FILE_SEARCH_STORE_NAME"]
        }
      }
    ],
    "generationConfig": {
"responseFormat": {
  "text": {
    "mimeType": "application/json",
    "schema": {
            "type": "object",
            "properties": {
                "amount": {"type": "string", "description": "The numerical part of the amount."},
                "currency": {"type": "string", "description": "The currency of amount."}
  }
}
},
            "required": ["amount", "currency"]
        }
    }
  }'
مدلهای پشتیبانیشده
مدلهای زیر از «جستجوی فایل» پشتیبانی میکنند:
| مدل | جستجوی فایل |
|---|---|
| Gemini 3.8 Flash | ✔️ |
| Gemini 3.6 Flash | ✔️ |
| Gemini 3.5 Flash-Lite | ✔️ |
| پیشنمایش Gemini 3.1 Pro | ✔️ |
| Gemini 3.1 Flash-Lite | ✔️ |
| پیشنمایش Gemini 3 Flash | ✔️ |
| Gemini 2.5 Pro | ✔️ |
| Gemini 2.5 Flash-Lite | ✔️ |
ترکیبهای ابزار پشتیبانیشده
مدلهای Gemini 3 از ترکیب ابزارهای داخلی (مثل «جستجوی فایل») با ابزارهای سفارشی (فراخوانی تابع) پشتیبانی میکنند. در صفحه ترکیبهای ابزار بیشتر بدانید.
انواع فایلهای پشتیبانیشده
«جستجوی فایل» از طیف وسیعی از قالبهای فایل که در بخشهای زیر فهرست شدهاند پشتیبانی میکند.
انواع فایل برنامه
application/dartapplication/ecmascriptapplication/jsonapplication/ms-javaapplication/mswordapplication/pdfapplication/sqlapplication/typescriptapplication/vnd.curlapplication/vnd.dartapplication/vnd.ibm.secure-containerapplication/vnd.jupyterapplication/vnd.ms-excelapplication/vnd.oasis.opendocument.textapplication/vnd.openxmlformats-officedocument.presentationml.presentationapplication/vnd.openxmlformats-officedocument.spreadsheetml.sheetapplication/vnd.openxmlformats-officedocument.wordprocessingml.documentapplication/vnd.openxmlformats-officedocument.wordprocessingml.templateapplication/x-cshapplication/x-hwpapplication/x-hwp-v5application/x-latexapplication/x-phpapplication/x-powershellapplication/x-shapplication/x-shellscriptapplication/x-texapplication/x-zshapplication/xmlapplication/zip
انواع فایل نوشتاری
text/1d-interleaved-parityfectext/REDtext/SGMLtext/cache-manifesttext/calendartext/cqltext/cql-extensiontext/cql-identifiertext/csstext/csvtext/csv-schematext/dnstext/encaprtptext/enrichedtext/exampletext/fhirpathtext/flexfectext/fwdredtext/gff3text/grammar-ref-listtext/hl7v2text/htmltext/javascripttext/jcr-cndtext/jsxtext/markdowntext/mizartext/n3text/parameterstext/parityfectext/phptext/plaintext/provenance-notationtext/prs.fallenstein.rsttext/prs.lines.tagtext/prs.prop.logictext/raptorfectext/rfc822-headerstext/rtftext/rtp-enc-aescm128text/rtploopbacktext/rtxtext/sgmltext/shaclctext/shextext/spdxtext/stringstext/t140text/tab-separated-valuestext/texmacstext/trofftext/tsvtext/tsxtext/turtletext/ulpfectext/uri-listtext/vcardtext/vnd.DMClientScripttext/vnd.IPTC.NITFtext/vnd.IPTC.NewsMLtext/vnd.atext/vnd.abctext/vnd.ascii-arttext/vnd.curltext/vnd.debian.copyrighttext/vnd.dvb.subtitletext/vnd.esmertec.theme-descriptortext/vnd.exchangeabletext/vnd.familysearch.gedcomtext/vnd.ficlab.flttext/vnd.flytext/vnd.fmi.flexstortext/vnd.gmltext/vnd.graphviztext/vnd.hanstext/vnd.hgltext/vnd.in3d.3dmltext/vnd.in3d.spottext/vnd.latex-ztext/vnd.motorola.reflextext/vnd.ms-mediapackagetext/vnd.net2phone.commcenter.commandtext/vnd.radisys.msml-basic-layouttext/vnd.senx.warpscripttext/vnd.sositext/vnd.sun.j2me.app-descriptortext/vnd.trolltech.linguisttext/vnd.wap.sitext/vnd.wap.sltext/vnd.wap.wmltext/vnd.wap.wmlscripttext/vtttext/wgsltext/x-asmtext/x-bibtextext/x-bootext/x-ctext/x-c++hdrtext/x-c++srctext/x-cassandratext/x-chdrtext/x-coffeescripttext/x-componenttext/x-cshtext/x-csharptext/x-csrctext/x-cudatext/x-dtext/x-difftext/x-dsrctext/x-emacs-lisptext/x-erlangtext/x-gff3text/x-gotext/x-haskelltext/x-javatext/x-java-propertiestext/x-java-sourcetext/x-kotlintext/x-lilypondtext/x-lisptext/x-literate-haskelltext/x-luatext/x-moctext/x-objcsrctext/x-pascaltext/x-pcs-gcdtext/x-perltext/x-perl-scripttext/x-pythontext/x-python-scripttext/x-r-markdowntext/x-rsrctext/x-rsttext/x-ruby-scripttext/x-rusttext/x-sasstext/x-scalatext/x-schemetext/x-script.pythontext/x-scsstext/x-setexttext/x-sfvtext/x-shtext/x-siestatext/x-sostext/x-sqltext/x-swifttext/x-tcltext/x-textext/x-vbasictext/x-vcalendartext/xmltext/xml-dtdtext/xml-external-parsed-entitytext/yaml
محدودیتها
- Live API: «جستجوی فایل» در Live API پشتیبانی نمیشود.
- عدم سازگاری ابزار: «جستجوی فایل» درحالحاضر نمیتواند با ابزارهای دیگر مثل زمینهسازی با «جستجوی Google»، زمینه نشانی وب، و غیره ترکیب شود.
محدودیتهای نرخ
«میانای برنامهسازی کاربردی جستجوی فایل» برای اعمال پایداری سرویس محدودیتهای زیر را دارد:
- حداکثر اندازه فایل / حد مجاز برای هر سند: ۱۰۰ مگابایت
- اندازه کل فضای ذخیرهسازی «جستجوی فایل پروژه» (براساس سطح کاربر):
- رایگان: ۱ گیگابایت
- سطح ۱: ۱۰ گیگابایت
- سطح ۲: ۱۰۰ گیگابایت
- سطح ۳: ۱ ترابایت
- توصیه: برای اطمینان از تأخیرهای بهینه بازیابی، اندازه هر فروشگاه «جستجوی فایل» را به کمتر از ۲۰ گیگابایت محدود کنید.
قیمتگذاری
- هزینه جاسازیها در زمان نمایهگذاری براساس قیمتگذاری جاسازی موجود از شما کسر میشود.
- فضای ذخیرهسازی رایگان است.
- جاسازیهای زمان پُرسمان رایگان است.
- هزینه نشانهای سند بازیابیشده بهعنوان نشانهای زمینهای معمولی محاسبه میشود.
قدم بعدی چیست
- به مرجع API برای File Search Stores (فروشگاههای جستجوی فایل) و File Search Documents (اسناد) مراجعه کنید.